 ™
Drex 1.5 vs Decision-1: The Models That Score, Not Write
Decision models became October's hottest new category: Nace.AI open-sourced Drex 1.5, an 8.95B scoring model, while Microsoft countered with Decision-1, a closed service post-trained from Qwen3.5-9B — both output option probabilities, never text.
Latest
1 updates · newest first-
Compare published: Drex 1.5 vs Decision-1.
Further updates will appear here
Side by side
✓ marks the side that wins the row| Item | Drex 1.5 | Decision-1 |
|---|---|---|
| Publisher & date | Nace.AI, launched around October 9, 2026 (OpenRouter lists Oct 9) | Microsoft, October 9, 2026 (Command Line blog) |
| Price | $0.04 input / $0 output per million tokens (OpenRouter)✓ | $0.042 input / output free per million tokens (Microsoft) |
| Context | 16,384 default, up to 131,072 (model card)✓ | 32,768 (Microsoft) |
| Openness | Open weights under Nace.AI Open RAIL-M; runs locally on one GPU or a Mac✓ | Hosted API only (Microsoft Foundry, OpenRouter); no open weights |
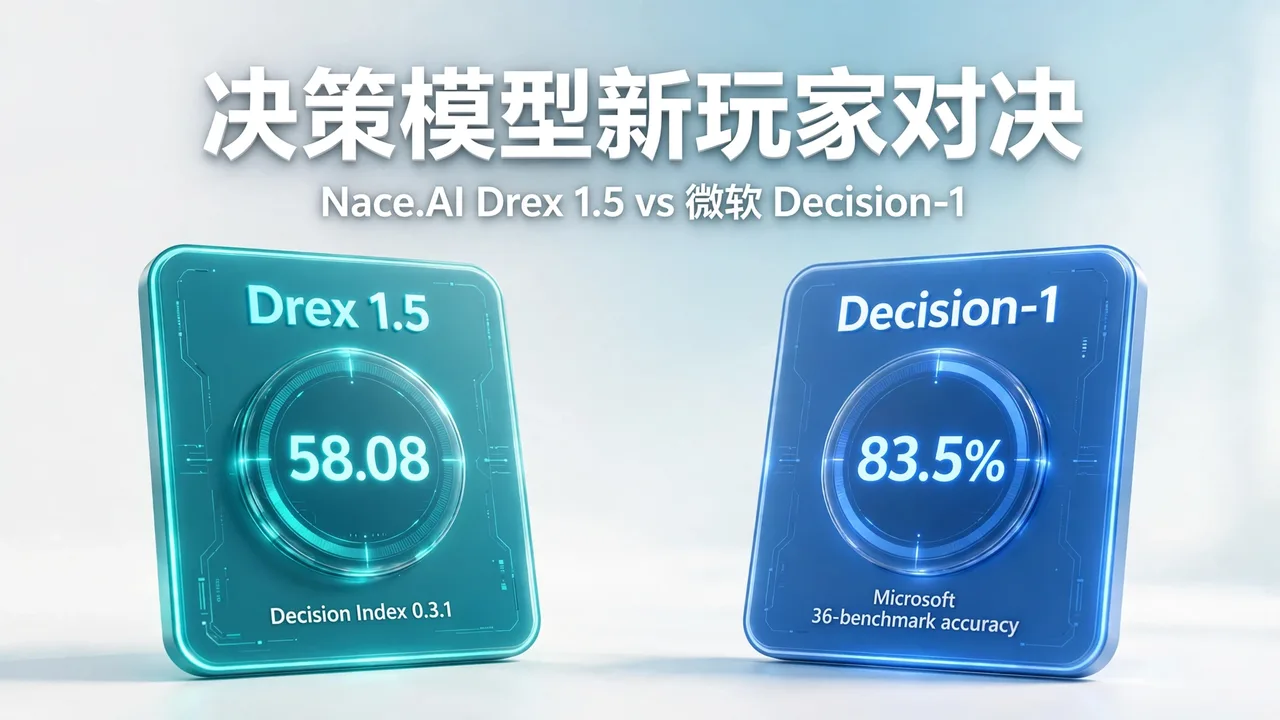
| Vendor-reported benchmark | 58.08 on Decision Index 0.3.1 (Nace model card) | 83.5% average accuracy across 36 benchmarks, highest in Microsoft's test (Microsoft internal testing) |
Verdict
How to choose: for local deployment or weight modification, look at Drex 1.5 (open weights, runs on one GPU); for a Microsoft-hosted low-latency scoring service, look at Decision-1 (85ms P50, free output).
01What they are
Drex 1.5 is the decision model Nace.AI released around October 9, with 8.95 billion parameters and open weights (Nace.AI Open RAIL-M license). It generates no text: given a state (text or JSON) plus typed questions (choice, yes/no, ordinal score), a single forward pass returns a calibrated probability for each option via POST /v1/systemone, compatible with TypeSafe's Jev decision API. Default context is 16,384 tokens, expandable to 131,072; bf16 weights are about 18GB, runnable on one CUDA GPU, and a 9.5GB Q8_0 GGUF build runs on Apple silicon or CPU.
Decision-1 is the decision-scoring model Microsoft announced October 9 on its Command Line blog, post-trained from Alibaba's Qwen3.5-9B; Microsoft says it will later rebase it on its own models and OpenAI's. It is hosted-API only (Microsoft Foundry and OpenRouter) with no open weights; context is 32,768 tokens, input $0.042 per million tokens, output free. Microsoft reports the highest average accuracy, 83.5%, in a 36-benchmark comparison (nearly 150,000 questions kept blind from training), with 85ms P50 latency — 2.5x faster than H2O-Lightning-4B and 35x faster than GPT-6 Sol — all from Microsoft's internal testing.
02Side-by-side comparison
The table below compares public pricing, context, openness and vendor-reported benchmarks; note the two cite different benchmark suites, so the scores are not directly convertible.
03Key facts
- Launch: Drex 1.5 went live around October 9 (OpenRouter lists 2026-10-09); Microsoft announced Decision-1 on October 9 on its Command Line blog.
- Pricing: Drex 1.5 is $0.04 input / $0 output per million tokens on OpenRouter; Decision-1 is $0.042 input per million tokens with free output (Microsoft).
- Benchmarks: Drex 1.5 scores 58.08 on Decision Index 0.3.1 (Nace model-card data, highest under 10B parameters); Decision-1 averages 83.5% accuracy in Microsoft's 36-benchmark comparison (Microsoft internal testing). The suites differ and are not directly comparable.
- Openness: Drex 1.5 has open weights (RAIL-M license) and supports local deployment; Decision-1 is hosted-API only, with no open weights or local build.
Why it matters
two new 9B-class decision models arrived within a week — Drex 1.5 is open-weight and locally deployable, while Decision-1 runs as a Microsoft-hosted service at 85ms latency.
CompaniesMicrosoft
SourcesMarkTechPost (2026-10-09, source); OpenRouter (2026-10-09, source); Microsoft Command Line blog (2026-10-09, source); The Register (2026-10-10, source). This article is compiled from public information and does not constitute investment advice.
From HIMIAO Horizon · himiao.ai
Comments
Related
- Oct 10Microsoft Launches Decision-1, a Decision Model That Outputs Calibrated Probabilities, Not Text
- Oct 17Microsoft's MAI-Base-2 Completes Pre-Training: 2T-Parameter All-MoE Architecture, Trained 38 Days on 16,000 GB200s
- Oct 12Microsoft Unveils Maia 300, Its Third Custom AI Chip, With Deployments Possibly Topping One Million Next Year
- Oct 2Microsoft Ships Its Own Voice Stack: 60-Language Streaming Transcription + Seconds-Level Voice Cloning
- Oct 18Microsoft Copilot Studio Launches Agent Accounts: Own Credentials, Shared Business Memory, Auto Triggers
Today
Oct 19 Monday- Brief
- GitHubGitHub Weekly Vol.1: 8 Projects Worth Your Time
Tested or read — weeklyAll →
- Quiz
- Call
Latest news
All →- Oct 18Anthropic to Commit 5% of Shares to New Public Benefit Fund
- Oct 19Stably AI's Orca Tops GitHub Daily Trending: One Desktop App to Orchestrate 30+ Coding Agents
- Oct 19Jailbroken PS5 Becomes a Local AI Server: Qwen3.8-27B Hits ~20 tok/s, Small Models Top 100
- Oct 19Anthropic Internal Study: Junior Share of Technical Staff Falls to 14%, Meeting Time Up 20%
- Oct 18Claude Cracks 25-Year Cryptography Mystery in Half an Hour: NIST Curve Seeds Came From a 1997 Clock
- Oct 18OpenCode Hit by "Distillation Attack": API Keys of About 1.4% of Users Compromised