 ™
Drex 1.5 Review: A 9B Decision Model That Scores Options, Not Text
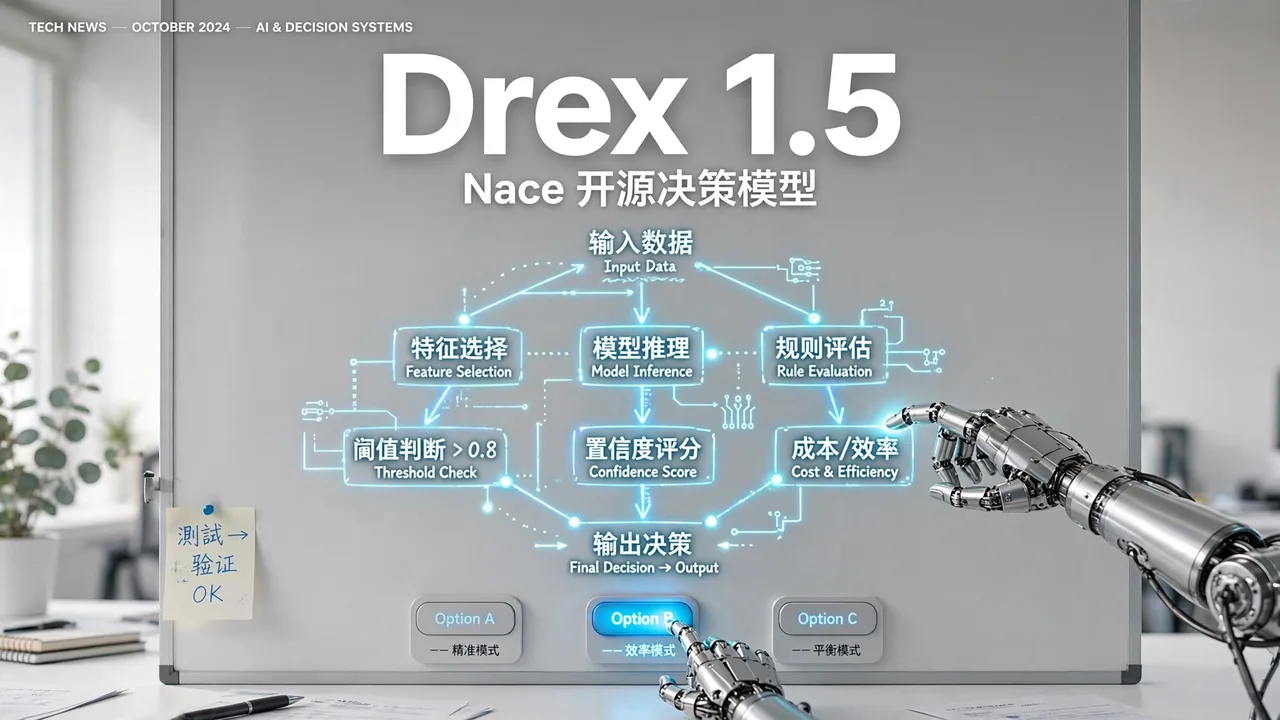
Nace.AI open-sourced Drex 1.5: an 8.95B model that writes nothing — feed it a state and typed questions, and one forward pass returns each option's probability. Its model card claims it tops the Decision Index public board under 10B parameters.
Scorecard
8.0/ 10
HIMIAO Horizon score
A new bar for open decision models: on par with Jev on public benchmarks, with knowledge gaps and license limits to note.
Pros
Highest public score under 10B parameters
Runs on a single GPU
Jev-compatible API, low migration cost
Cons
Public score is vendor-submitted and trained on benchmark training splits
Weaker than Jev on knowledge and science reasoning
Commercial use restricted by license
Best for
Developers building agent routing, ticket triage and tool dispatch who need local deployment
01What happened
Nace.AI open-sourced Drex 1.5 on October 8–9, 2026: 8.95B dense parameters, about 18GB of bf16 weights; a Q8_0 GGUF of about 9.5GB runs on Apple silicon and CPUs. Default context is 16,384 tokens, up to 131,072. Three question types: choice, noul (yes/no) and ordinal score. It serves POST /v1/systemone, the same request format as TypeSafe's Jev; Nace says existing Jev clients migrate by changing a few environment variables. The backbone is Qwen3_5ForCausalLM, based on XiaomiMiMo/MiMo-V2.6-Distill-Qwen-9B. License is Nace.AI Open RAIL-M: organizations with over $1M in yearly revenue or funding raised need a separate license beyond personal or research use.
02Testing and results
The basis is model-card figures plus independent testing. Model card (Nace's own run of the official kit on the full public suite): 58.08 on Decision Index 0.3.1 public (Jev 1.13.0 at 57.96, both inside the board's 0.9-point tie band; ahead of Jev on 20 of 37 benchmarks); Full score 50.84 (25th of 117 rows, Jev at 60.11); 86.2% on JevBench's 231 items (Jev at 87.0%). Caveat: the public score is vendor-submitted and trained on the benchmarks' training splits, so the Full score (including private tests Nace could not train on) is the fairer number. Independent test (dev.to, October 10, 2026, 82 decision questions run locally on a Mac via OpenRouter): Drex 72/82, Microsoft Decision-1 75/82, Jev 79/82, Perplexity Decider 27B 80/82; Drex median latency 0.679s, $0.0030 per 1,000 calls.
03Key facts
- Runnability: A single 24GB A10G runs bf16; the Q8_0 GGUF is about 9.5GB.
- Long docs: 93.4% accuracy at 32k–128k context (model card), 2.0s median latency.
- Weak spots: 45.4% on GPQA Diamond (Jev 78.6%); 7.4% per-review F1 on ACOS aspect sentiment.
- Hosted: On OpenRouter via DeepInfra at $0.04 per 1M tokens.
Why it matters
the decision-model category gets its first open weights on par with closed Jev, runnable on one GPU, cutting judging cost to $0.003 per 1,000 calls.
From HIMIAO Horizon · himiao.ai
Comments
Related
- Oct 13Drex 1.5 vs Decision-1: The Models That Score, Not Write
- Oct 17TypeSafe's Jev Becomes Vercel's Fastest-Adopted Model Ever, Reaching 35% of Paid Teams in Two Weeks
- Oct 10Microsoft Launches Decision-1, a Decision Model That Outputs Calibrated Probabilities, Not Text
- Oct 9TypeSafe Raises $870M Series A at $7.5B for Non-Text AI Model Jev
Today
Oct 19 Monday- Brief
- GitHubGitHub Weekly Vol.1: 8 Projects Worth Your Time
Tested or read — weeklyAll →
- Quiz
- Call
Latest news
All →- Oct 19Meta Muse Spark Open Review: 816B Open Weights, Leading Agent Tool Use
- Oct 19MONST3R-AI Crimeware Runs Autonomous Pentest Scans on Stolen API Keys, Victims Foot the Bill
- Oct 19VoiceStudio Hits No. 3 on GitHub Daily Trending: Open-Source, Fully Local ElevenLabs Alternative
- Oct 19dsh Free-Model Plugin Hits No. 2 on GitHub Daily Trending: Frontier Models Without Login or API Key
- Oct 18Anthropic to Commit 5% of Shares to New Public Benefit Fund
- Oct 19Stably AI's Orca Tops GitHub Daily Trending: One Desktop App to Orchestrate 30+ Coding Agents